

The process of designing hypergraphs is still hotly debated in modelling circles, though, for the most part, it comes down to two distinct approaches: encyclopedic (or topical) organisation vs historical (or event-driven) organisation. This distinction becomes increasingly important and relevant as graphs are seen as the underlying layer for the effective use of artificial intelligence systems.
The term knowledge graph first emerged around 2015. A knowledge graph, for the most part, can be seen as topical in nature: you define classes of things, each of which has a specific structure, with properties that connect various things together. At a very fundamental level, Wikipedia can be seen as a knowledge graph, relating topical entities, with an underlying classification, and the translation between Wikipedia and its related siblings, Wikipedia, and DBpedia, can be seen by the fact that all of these focus on topics - articles of interest and how they interrelate.
The term context graph, on the other hand, emerged more recently (within the last year or two) and was originally defined from the perspective of business processes (with a strong emphasis on how these are essential parts of generative AI-based transformers). However, this particular viewpoint has shifted as the term has gained more currency and can increasingly be seen as a different organisational model of information for hypergraphs, one based not on topics but on events.
In this view of modelling, most things can be seen from the perspective of events. An event is an occurrence of something in time. The closest analogy in the physical world would be a newspaper. A newspaper article is a piece of news (novel information) that is structured in a certain way:
When did the event occur (siting in time)
Where did the event occur (siting in space)
Who reported the event (who is the author or authority)
How is the event summarised (title, subtitle, abstract, etc)
What was the significance of the event (why is it being reported)
Who or what was the subject of the event
How was the event classified
How was the event related to other events
How reliable is the author of the event
Who were the agents involved in the event
What were the observations of the event
When was the event reported (vs. when did it occur)
What is expected to happen next
This kind of event structure differs from the more topical, curated approach of a Wikipedia article because its focus is on capturing facts (ground truth) first, and only secondarily on the structural relationships of information. Beyond news reporting, a context graph can also be seen in different areas of focus:
Decision Tracing. Organisation communications - meetings, emails, announcements, etc. - follow a context model rather than a topical model. The challenge here has primarily been in capturing these events as metadata.
Supply Chain Management. A supply chain system can be viewed as a series of messages from different reporting entities indicating that specific events have occurred, such as packages being shipped, transferred, received, deferred, or lost. The exact definitions of those packaged things are certainly important, but secondary to their status at any given time.
Research. In most research organisations, discovery is not a single thing so much as a series of events (a log) consisting of tests (observations) and their results (artefacts), along with their ultimate disposition.
Narratives. A story or novel (or movie) can be seen as a series of unfortunate events, tied together as a sequence that is usually referred to as a plot.
Business Process Orchestration. A context graph describes rather than prescribes, but it can serve as a basis for intended events and their unfolding. This becomes especially important in distributed or orchestrated agentic systems.
Medical Histories in Patient Records. A patient medical record is a series of events - intake, doctor visits, tests, prognoses, treatments and so on.
Many, many others. In essence, a context graph is a graph of history, rather than of theme.
This doesn't necessarily change the data itself, but it does affect how that data is modelled, as most things, perforce, become viewed through the lens of being events.
Event-Based Modelling
Event-based modelling has traditionally been difficult to perform in RDF because you were generally not describing objects, but rather were discussing (annotating) assertions. With the new RDF-Star specification and the updated Turtle syntax, this becomes more feasible.
Journalistic News
The following illustrates a journalistic event:
@prefix : <http://example.org/ctx/> .
@prefix cg: <http://example.org/contextgraph/> .
@prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#> .
@prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#> .
@prefix xsd: <http://www.w3.org/2001/XMLSchema#> .
@prefix time: <http://www.w3.org/2006/time#> .
@prefix geo: <http://www.w3.org/2003/01/geo/wgs84_pos#> .
@prefix prov: <http://www.w3.org/ns/prov#> .

# ============================================
# Upper Ontology - Event Hierarchy
# ============================================

cg:Event a rdfs:Class ;
    rdfs:label "Event" ;
    rdfs:comment "An occurrence at a point or interval in time" .

cg:JournalisticEvent rdfs:subClassOf cg:Event .
cg:OrganizationalEvent rdfs:subClassOf cg:Event .
cg:LogisticsEvent rdfs:subClassOf cg:Event .
cg:ExperimentalEvent rdfs:subClassOf cg:Event .

# ============================================
# EVENT 1: Journalistic - Market Disruption
# ============================================

:evt_news_20240215_001 a cg:JournalisticEvent ;
    cg:occurredAt "2024-02-15T09:30:00-05:00"^^xsd:dateTime ;
    cg:reportedAt "2024-02-15T14:22:00-05:00"^^xsd:dateTime ;
    cg:location :location_nyse_trading_floor ;
    cg:reportedBy :journalist_maria_santos ;
    cg:headline "Tech Sector Plunges 8% on Fed Rate Decision" ;
    cg:significance "Major market event affecting $2.3T in market capitalization" .

# Annotating the observation triple
:evt_news_20240215_001 cg:observation [
    cg:nasdaqChange -8.2 ;
    cg:sp500Change -5.7
] ~ {|
    prov:wasDerivedFrom :bloomberg_terminal_feed ;
    cg:confidence 1.0 ;
    cg:dataQuality :authoritative
|} .

# Annotating the reportedBy relationship
:evt_news_20240215_001 cg:reportedBy :journalist_maria_santos ~ {|
    cg:reporterCredentials "15 years financial journalism" ;
    cg:reliabilityScore 9 ;
    prov:hadRole :primary_author
|} .
In this case, the event is a story talking about an 8% plunge in the NYSE exchange market (it may contain the bulk of the story as well, but for purposes of discussion, larger text isn’t incorporated). The event in question provides both the date and time, the author of the piece, and an indicator of significance. It also incorporates an observation - the change in the NASDAQ and S&P 500 indexes, as well as provenance information - the data came from a Bloomberg terminal, and the annotation incorporates an indication of the reporter’s credibility.
Note that while some of this is in a (temporary) example namespace, prov-o is also used to provide provenance-related information. The specific ontologies used in a context graph are secondary to the overall design of an event-driven architecture.
A Board Meeting with Decisions
A second example shows an organisational event: a board meeting.
# ============================================
# EVENT 2: Organizational - Strategic Decision
# ============================================

:evt_meeting_20240216_003 a cg:OrganizationalEvent ;
    cg:occurredAt “2024-02-16T10:00:00-08:00”^^xsd:dateTime ;
    cg:reportedAt “2024-02-16T12:30:00-08:00”^^xsd:dateTime ;
    cg:location :acme_hq_boardroom_12a ;
    cg:reportedBy :exec_assistant_david_kim ;
    cg:theme concept:Products, concept:Compensation, concept:Ethics ;
    cg:headline “Executive Committee Approves AI Ethics Framework” ;
    .

# Annotating the participant relationship
:evt_meeting_20240216_003 cg:participant :cto_sarah_patel ~ {|
    cg:participationRole “Presenter - AI Ethics Framework” ;
    prov:hadRole :presenter
|} .

# Annotating the observation
:evt_meeting_20240216_003 cg:observation [
    cg:motionText “Adopt AI Ethics Framework version 1.0 as presented” ;
    cg:relevantTo :evt_meeting_20240119_001 ;
    cg:voteType :unanimous
] ~ {|
    cg:legallyBinding true ;
    cg:recordedBy :exec_assistant_david_kim ;
    cg:witnessedBy :legal_counsel_amanda_johnson
|} .

# Using a reifier explicitly
:evt_meeting_20240216_003 cg:reportedBy :exec_assistant_david_kim ~ :reporter_stmt {|
    cg:reporterRole “Executive Assistant to CEO” ;
    cg:reliabilityScore 10 ;
    prov:hadRole :official_recorder
|} .
Again, the organisation event is a subclass of the general event property, indicating the who/what/when/where/why approach of most events. Several key associations, including participant and reporter information, are provided alongside reifications that describe provenance.
Notice within the cg:observation block that there is a back reference:
:evt_meeting_20240216_003 cg:relevantTo :evt_meeting_20240119_001 .
One important aspect of events is that you can create relevant backchains to other events. This can make it possible to determine the evolution of a particular decision over time through the use of transitive closure, one of the things that gives context graphs so much power.
Another related aspect is the ability to differentiate start and stop events in order to better ascertain intervals and durations. Especially when combined with provenance, this can go a long way toward explaining why a process started and why it was eventually stopped, key information for examining the reasons things happened, rather than the fact that they did.
Logistics
Logistics, by its very nature, is driven: you’re tracking when things arrived where, what those things were, and what caused them to enter into error conditions (such as arriving late). Again, while resources play a role, the graph is built with a focus on events.
# ============================================
# EVENT 3: Logistics - Supply Chain Status
# ============================================

:evt_shipment_20240217_782 a cg:LogisticsEvent ;
    cg:occurredAt “2024-02-17T06:42:00Z”^^xsd:dateTime ;
    cg:reportedAt “2024-02-17T06:42:03Z”^^xsd:dateTime ;
    cg:location :port_rotterdam_terminal_4 ;
    cg:reportedBy :system_maersk_track_trace ;
    cg:headline “Container MSCU7654321 Departed Rotterdam” .

# Annotating the observation
:evt_shipment_20240217_782 cg:observation [
    cg:containerNumber “MSCU7654321” ;
    cg:weight 28400
] ~ {|
    cg:dataSource :automated_weighing_system ;
    sh:units Units:MetricTons ;
    cg:confidence 1.0 ;
    prov:wasGeneratedBy :system_terminal_operating_system
|} .

# Annotating with automatic blank node reifier
:evt_shipment_20240217_782 cg:reportedBy :system_maersk_track_trace ~ {|
    cg:systemVersion “MaerskAPI v2.3.1” ;
    cg:reliabilityScore 10 ;
    cg:automationLevel :fully_automated
|} .

# Annotating the causedDelay relationship
:evt_shipment_20240217_782 cg:causedDelay :evt_weather_delay_20240214 ~ {|
    cg:delayDuration “P3D”^^xsd:duration ;
    cg:delayCause “Storm Karlotta - wind speeds exceeded safe loading limits” ;
    cg:delayClassification :force_majeure
|} .
Notice that reifications can also serve to qualify units for specific literal quantities.
Research
An event model usually includes a mechanism for capturing observations. This can be a major factor in developing time-series data, even when that data is asynchronous and sporadic.
# ============================================
# EVENT 4: Experimental - Research Observation
# ============================================

:evt_experiment_20240218_exp441 a cg:ExperimentalEvent ;
    cg:occurredAt “2024-02-18T13:25:00-05:00”^^xsd:dateTime ;
    cg:reportedAt “2024-02-18T18:15:00-05:00”^^xsd:dateTime ;
    cg:location :lab_biochemistry_mit_rm_714 ;
    cg:reportedBy :researcher_dr_emily_nakamura ;
    cg:headline “Protein XJ-441 Crystallization Successful” .

# Annotating the observation
:evt_experiment_20240218_exp441 cg:observation [
    cg:resolutionLimit 2.8 ;
    cg:diffractionQuality :excellent
] ~ {|
    cg:measuredBy :postdoc_james_martinez ;
    sh:units Units:Angstroms ;
    cg:instrument “Rigaku HomeFlux diffractometer” ;
    cg:confidence 0.9 ;
    cg:preliminaryData true
|} .

# Annotating the reporter
:evt_experiment_20240218_exp441 cg:reportedBy :researcher_dr_emily_nakamura ~ {|
    cg:credentials “PhD Biochemistry (Stanford 2018)” ;
    cg:reliabilityScore 9 ;
    prov:hadRole :principal_investigator
|} .

# Annotating the significance assessment
:evt_experiment_20240218_exp441 cg:significance
    “Breakthrough: enables structure-function analysis for drug target validation” ~ {|
    cg:assessedBy :professor_susan_chen ;
    cg:commercialPotential :high ;
    cg:patentConsideration true
|} .

# Using reifiedTriple with reifier for cross-event relationships
:evt_shipment_20240217_782 cg:criticalFor :production_schedule_q2_2024 ~ :supply_risk {|
    :riskLevel :medium ;
    :contingencyPlan :alternative_supplier_activated ;
    |} .
Context Graphs and Data Organisation
One interesting consequence of working with event-driven models is that there is a clear starting point for the serialisation of a given graph into a narrative stream.
For instance, the journalism scenario given above, rendered as a diagram, looks as follows:
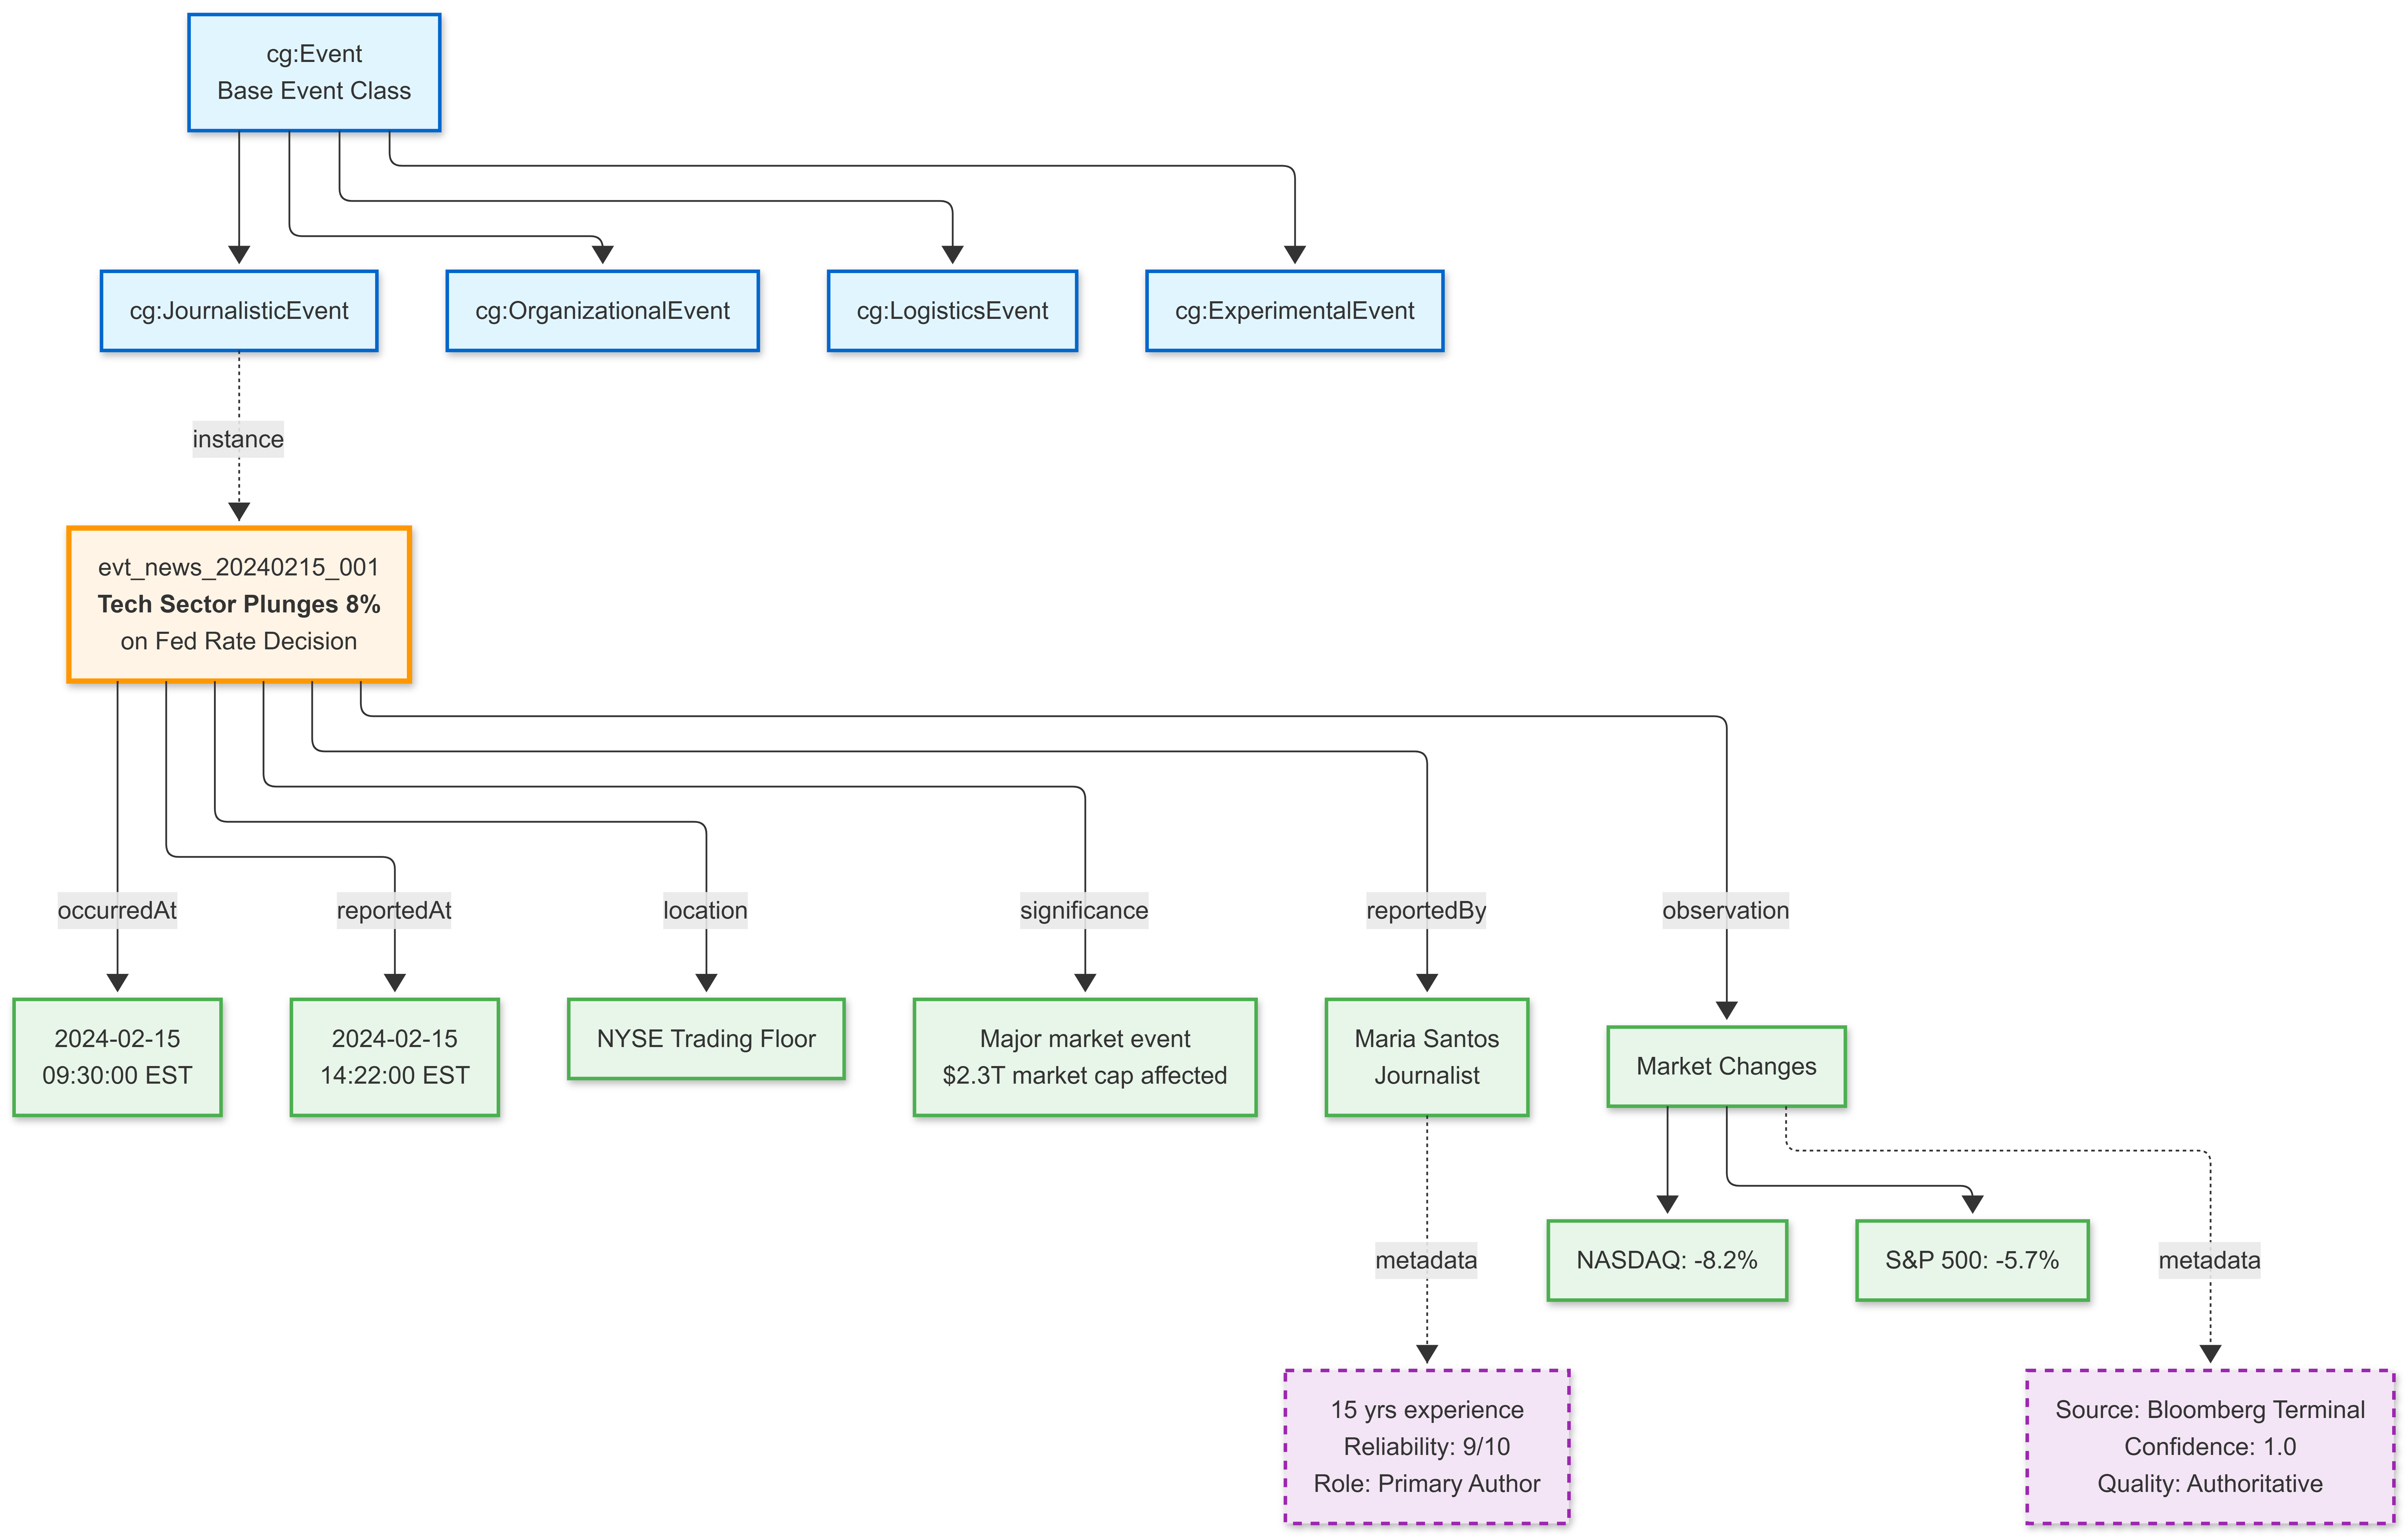
This can be serialised simply by following the graph in a recursive descent:
The Market Disruption Event
On February 15th, 2024, a significant JournalisticEvent occurred, identified as evt_news_20240215_001.
This event occurred at 9:30 AM Eastern Time on that morning, though it was not reported until 2:22 PM that same afternoon. The event took place at the NYSE Trading Floor in New York.
The event carried the headline: “Tech Sector Plunges 8% on Fed Rate Decision” and held particular significance as a major market event affecting $2.3 trillion in market capitalisation.
The Reporter Attribution
The event was reported by journalist Maria Santos. This reporting relationship adds context: Maria Santos brings 15 years of financial journalism experience to her coverage, maintains a reliability score of 9 out of 10, and served as the primary author of this story.
The Market Observations
The event included quantitative observations of market changes: the NASDAQ fell 8.2 per cent while the S&P 500 declined 5.7 per cent. These observations were derived from the Bloomberg Terminal feed and carry a confidence level of 1.0 (absolute certainty), with data quality rated as authoritative.
This ability to serialise the graph is important for a few reasons:
With a knowledge graph, there is a structure there, but serialising as natural language doesn’t always make sense. With a context graph, serialising content maps very closely to graph structure, particularly if you view the event as being the starting point.
Reifications are subordinate clauses (typically but not always prepositional phrases) in sentences, and blank nodes (bracketed expressions) are usually indirect clauses starting with words such as that or which.
This breakdown becomes especially important with RAG, as more natural-language structures ensure higher fidelity in LLM output when fed into a context window.
If you iterate forward on a property such as cg:relevantTo, you effectively follow a causal chain that will tell an evolving story about a particular event. This is occasionally referred to as a decision trace, but it’s more properly an event trace, with decisions simply being one form of an event.
Event traces are not necessarily trees; rather, they form something more akin to a river, as a given event may both be influenced by and influence multiple other events over time. The cg:relevantTo property has an inverse property cg:influences that flips the back arrow to a forward one, but is usually assigned after the cg:relevantTo. This turns the event traces into an influence map of narratives:
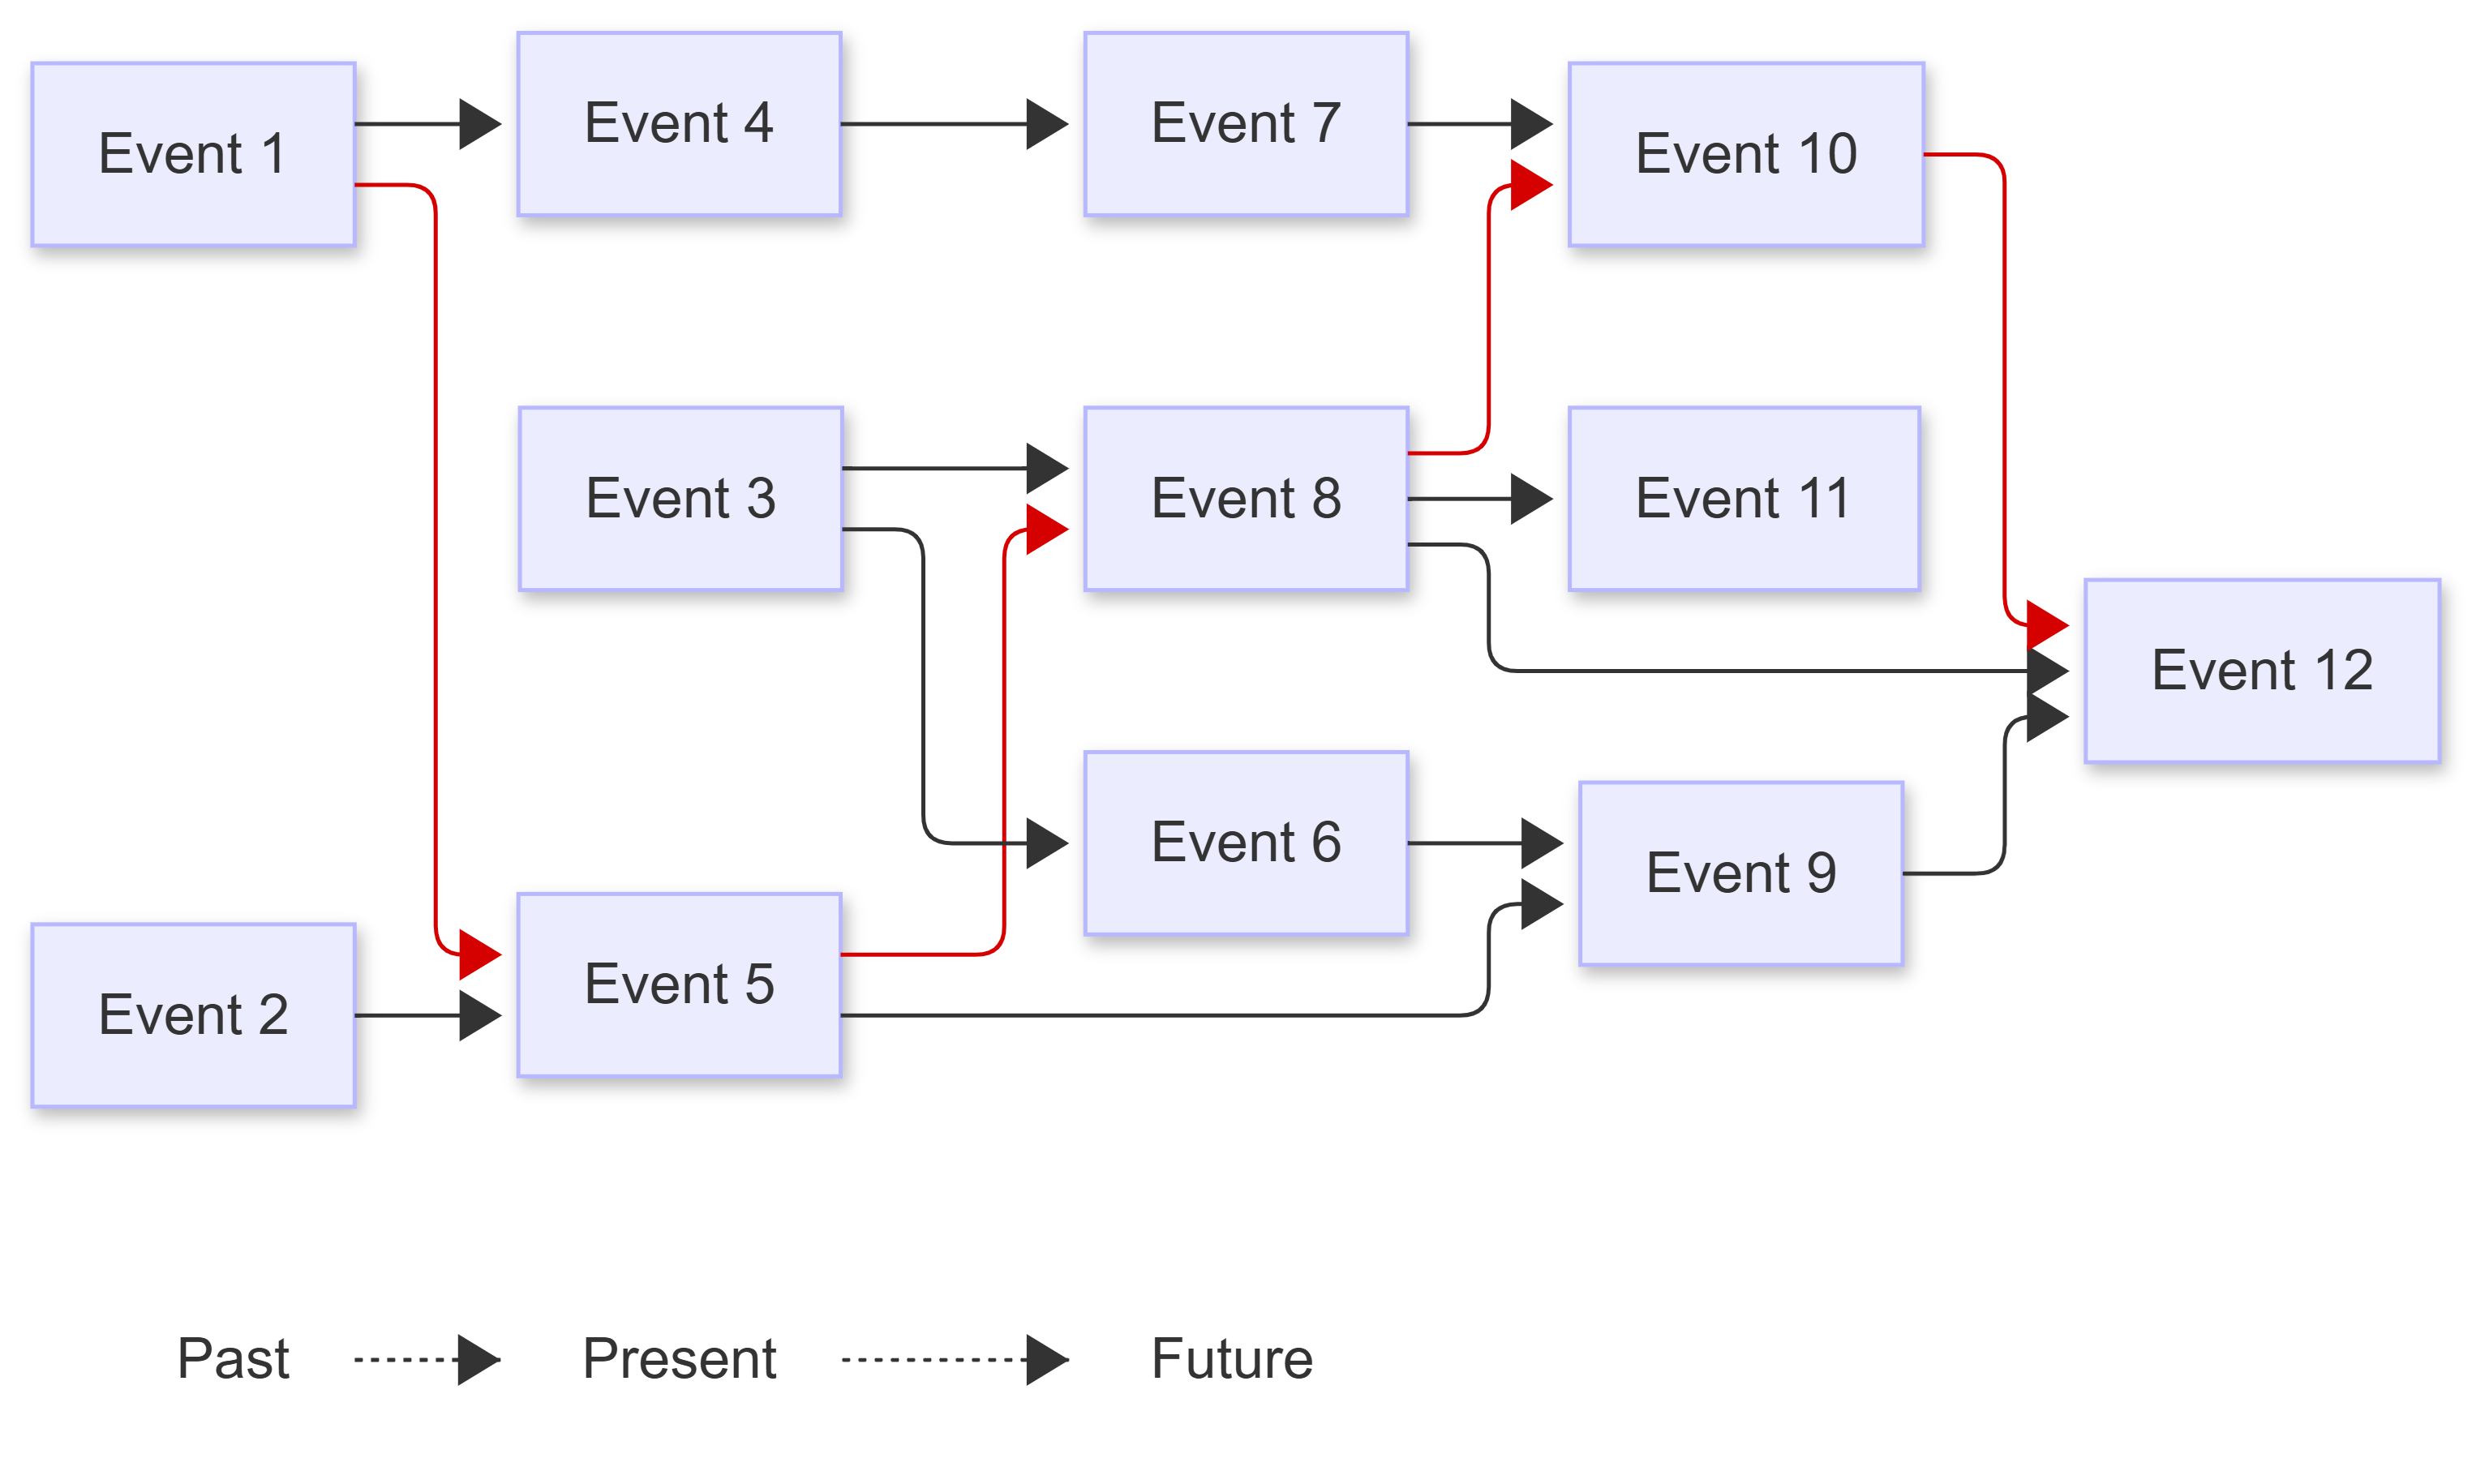
A narrative in this scheme can then be seen as the path or paths between two given events, such as the red path in the diagram shown here. These aren’t necessarily purely causal; rather, a narrative can also be interpreted (perhaps more accurately) as a path of influence on a given event.
In retrospect, one can assign degrees of influence (Bayesian priors) to any given cg:influences assertion with the cumulative weights going out of any node always equaling 100%:
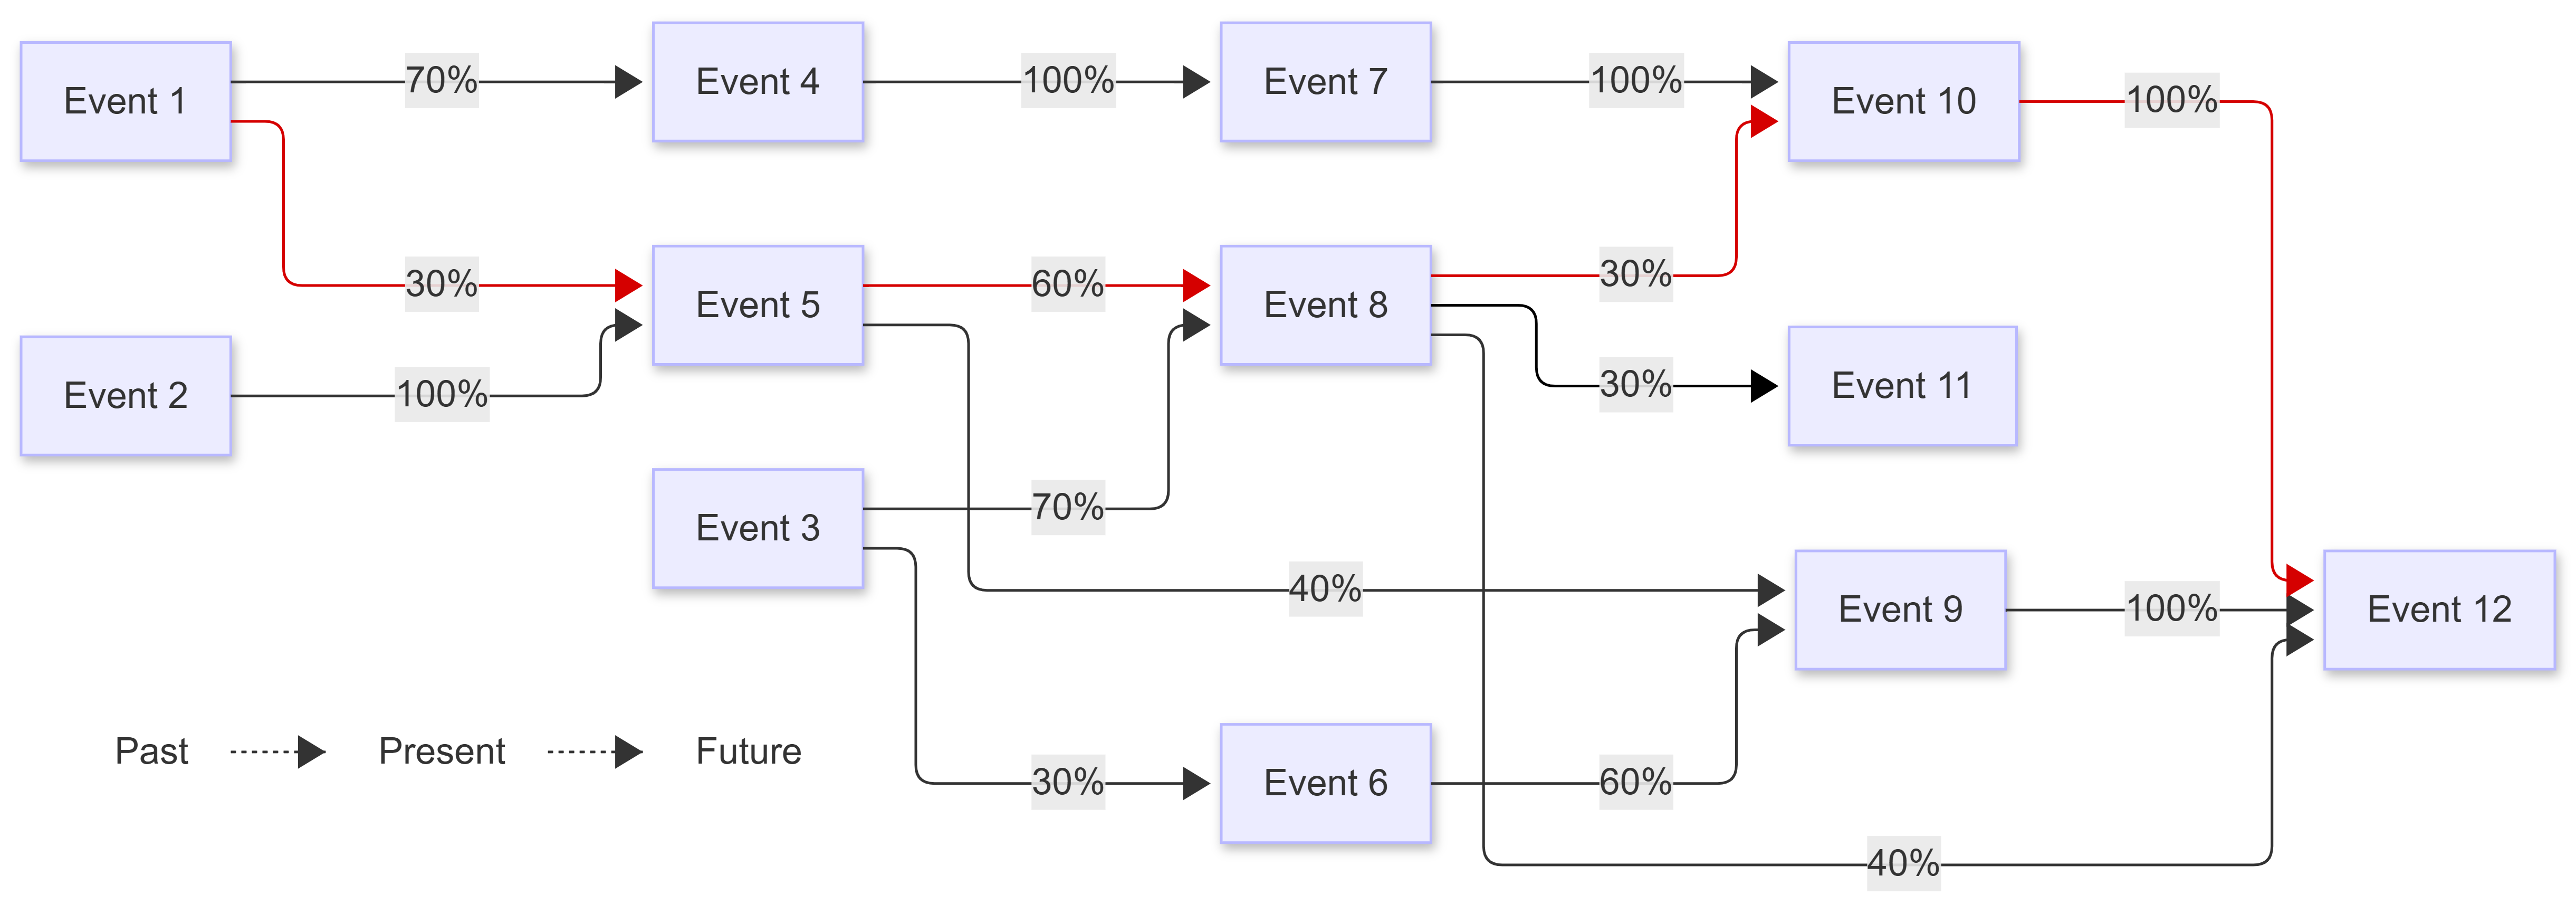
Again these are calculated after the fact, but they can actually make performing Bayesian analysis considerably easier by doing similarity analysis on events to find that are most like existing nodes, then using that to do relevant likelihood calculations in other cases. For instance, the likelihood of having the sequence Event1, Event5, Event8 and Event12 occur becomes 30% x 60% x 30% x 50% or around 5.4%, while Event 11 becomes the sum of the Bayesian paths 1 → 5 → 8 → 11 (5.4%) and 2 → 5 → 8 → 11 (18%) or 23.4%. The Bayesians themselves can be added as annotations:
  Event:Event1 Event:influences Event:Event4 ~ {|
      Influence:weight 0.70;
      Influence:determinedBy Person:janeDoe ;
      Influence:hasAnalysis Analysis:AN-JD-164 ;
      ;|} .
Note the use of influence:hasAnalysis here. Bayesians are basically guesses, and each analyst of a given graph is likely to come up with different values based upon their own particular metrics and methodologies. By noting which analysis a Bayesian comes from, you can have the same influence link be given different metrics, and can then choose in your queries to use one analysis over another (or to create an analysis that reflects an average or consensus view), i.e.,
  Event:Event1 Event:influences Event:Event4 ~ _:JaneDoesAnalysis1-4 {|
      Influence:weight 0.70;
      Influence:determinedBy Person:janeDoe ;
      Influence:hasAnalysis Analysis:AN-JD-164 ;
      ;|},
    _:JamesJonesAnalysis1-4 {|
      Influence:weight 0.63;
      Influence:determinedBy Person:JamesJones ;
      Influence:hasAnalysis Analysis:AN-JJ-5351 ;
      ;|}
 .
Summary
Context Graphs are hypergraphs, just as knowledge graphs are. Their primary difference is in how they are modelled. Knowledge graphs are encyclopedic and topical, context graphs are historical and event driven. Context graphs more closely match conventional narrative structures, whether one is talking about collections of news articles, decisions made in an organisation, movement of goods in a supply chain, progressions of a disease in a medical history or elsewhere. Events are not necessarily purely causal, but they can be analysed for their influence on one another, and these can be quantified as Bayesian priors.
Context graphs also benefit strongly from reification, making it possible to interpret events in different ways and determine the extent to which events are captured and utilised to enhance learning, both in human terms and in building better neural models. As such, you should see them as a tool to understand the evolution of systems over time.
In Media Res,
If you like these articles, please consider becoming a paid subscriber. It helps support me so that I can continue writing code, in-depth analyses, educational pieces, and more.
Check out my LinkedIn newsletter, The Cagle Report.
I am also currently seeking new projects or work opportunities. If anyone is looking for a CTO or Director-level AI/Ontologist, please get in touch with me through my Calendly:
If you want to shoot the breeze or have a cup of virtual coffee, I have a Calendly account at https://calendly.com/theCagleReport. I am available for consulting and full-time work as an ontologist, AI/Knowledge Graph guru, and coffee maker. Also, for those of you whom I have promised follow-up material, it’s coming; I’ve been dealing with health issues of late.
I’ve created a Ko-fi account for voluntary contributions, either one-time or ongoing, or you can subscribe directly to The Ontologist. If you value my articles, technical pieces, or general reflections on work in the 21st century, please consider contributing to support my work and allow me to continue writing.
Nice breakdown. I guess I should generate a live instance of these graphs directly from this post :)
In practice, I have found the need to model both topical and event-driven concepts in the field of the built environment.
For example, modeling the composition and topology of a system (topical):
asset1 hasLocation room1
asset1 feeds asset2
Followed by modeling the work that is performed on an asset (event-driven):
workorder1 pertainsTo asset1
This article gave me the impression that it's one or the other. Why not both?